Cutting Costs and Boosting Efficiencies with RAG-Powered Document Search
Our GenAI team built a RAG-powered search and translation system for a global leader in digital content.
Overview
Businesses in the digital content space deal with huge volumes of documents, knowledge assets, and user resources, and these keep growing every year. As the volume grows, it becomes harder for users to find, understand, and interact with the information they need. Traditional keyword search and manual navigation often fall short, which leads to slower discovery, a poor user experience, and lower engagement.
One of our clients, a global leader in digital content, was facing a similar problem. Let’s see how the DivIniSoft GenAI team helped the client overcome it with a RAG-powered solution.
Challenges
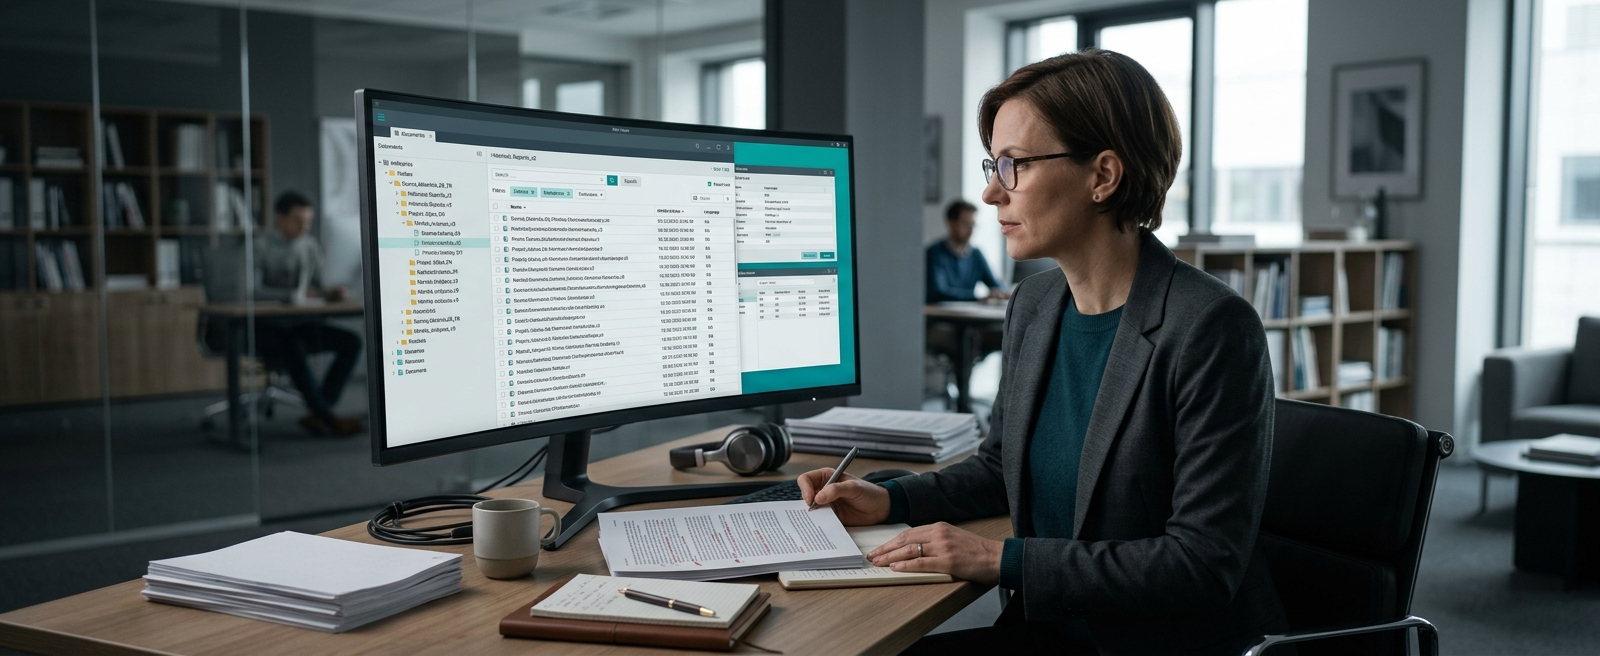
The client manages large document repositories that are read by users across multiple regions and languages. The client had also partnered with a third-party translation service. With every document now copied into several languages, the size and complexity of the repository grew very quickly, and finding information in it became even harder.
Here’s the list of problems the client faced as the repository kept growing but the technology stack stayed the same:
- Users had to search large, multilingual repositories by hand, so they struggled to find relevant information quickly.
- Manual searching lowered user engagement and increased the time spent locating content.
- The third-party translation service brought high recurring costs and was hard to scale.
- Translated documents did not keep their original formatting, so the team spent extra hours reformatting them as per brand guidelines.
- The existing technology stack could not support real-time interaction with documents.
So, the client reached out to the DivIniSoft GenAI experts for an AI-driven system that could search documents efficiently and let users interact with them in real time. The client also needed an in-house, scalable translation solution that kept the original formatting and reduced their dependence on third-party translation providers.
Our Strategy
After analyzing the client’s service, data repository, and challenges, our GenAI experts recommended a solution based on RAG. It would speed up searching across documents and support accurate translation into different languages. For translation, the team chose a multilingual large language model (LLM) that could translate documents end to end while keeping contextual accuracy, consistent terminology, and the original document structure.
RAG, or Retrieval-Augmented Generation, is an AI framework that lets a GenAI system index millions of documents as vector embeddings. Relevant content is then retrieved by its meaning, rather than by matching keywords.
Our Solution
Here’s how we implemented the RAG solution for the client.
-
01
Document Conversion and Text Extraction
We first converted the documents into HTML/CSS files and used OCR to extract the information held in images. Then we used text extraction libraries to process the wide range of documents in the client’s repository, so they were ready for indexing. All the documents and processed outputs were stored in AWS S3, with automated workflows managing the storage.
-
02
AI-Powered Translation
We built a scalable workflow to translate the multilingual documents. The team used the GPT-4o model to translate each document end to end while keeping its original formatting. We also implemented a rolling context window, so the translation stays coherent from one page to the next and is easy to read.
-
03
Conversational Document Interaction
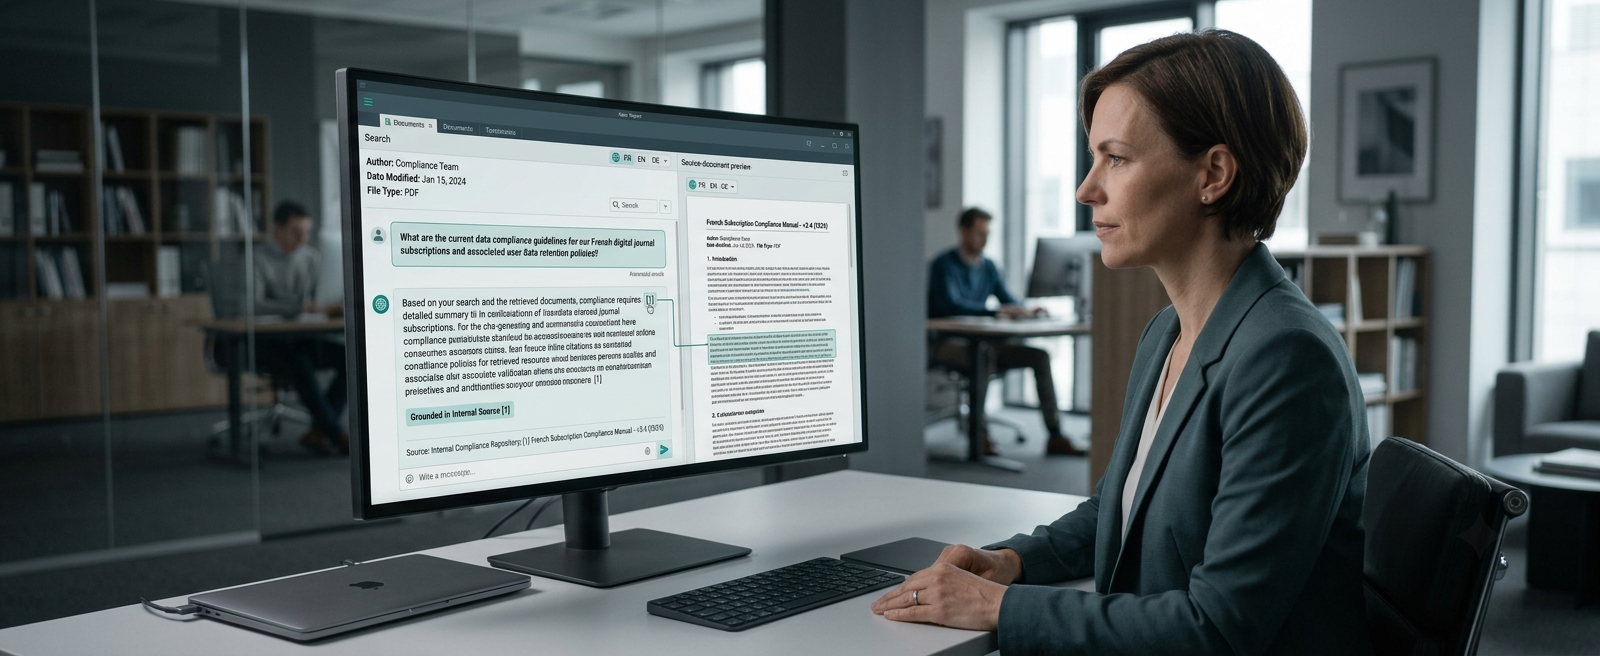
To make it easy to get information from documents across the repository, we deployed a conversational, RAG-powered system. We chose a chunking strategy that splits the content into logically meaningful sections. Each chunk was then converted into a semantic embedding using the text-embedding-3-large model, and the embeddings were stored in a Pinecone vector database.
Business Outcomes
- Cut the time users spent finding relevant information by more than 75%, through conversational document interaction.
- Reduced translation costs by 50%, as the in-house translation system lowered the dependence on third-party translators.
- Streamlined workflows through automation, which reduced manual effort and sped up the time-to-market for new features.
Tech Stack
Conclusion
By implementing a GenAI-powered document search and translation solution, our experts helped the client change the way users interact with large-scale digital content. The RAG system now supports faster information discovery, accurate multilingual translation, and a consistent document experience for all users.
GenAI can streamline content generation, ideation, document analysis, and intelligent search. If your teams work with large document repositories, let our experts find the areas in your workflow that can benefit most from GenAI and RAG solutions.